TokenDyno data: licence, citation and the public API
TokenDyno's leaderboard data is free to reuse under CC BY 4.0 — attribution is the only condition — and there is a public API with no key and no sign-up. Everything below is the whole of it: the licence in plain words, a citation line you can paste, the four public endpoints with example requests and a real response, and the exact coverage boundary.
What licence is the TokenDyno data under?
CC BY 4.0 — the Creative Commons Attribution 4.0 International licence. It covers the leaderboard, the per-model measurements and everything the API returns, including the embeddable badge image.
Attribution is the only condition. You may copy, redistribute and adapt this data, including commercially, as long as you credit TokenDyno and link to the licence. There is nothing else to satisfy.
The site's machine-readable signals say the same thing, and they are the same statement rather
than a second set of terms: robots.txt declares
Content-Signal: ai-train=yes, search=yes, ai-input=yes, every page carries a
Link header with rel="license" pointing at that deed, and the
homepage's Dataset structured data carries
license: https://creativecommons.org/licenses/by/4.0/.
How do I cite TokenDyno?
Paste this line and replace the bracketed date with the day you accessed the data:
TokenDyno. "Live LLM tokens-per-second leaderboard." https://tokendyno.com/. CC BY 4.0 (https://creativecommons.org/licenses/by/4.0/). Accessed [YYYY-MM-DD].
If you are citing one model rather than the board as a whole, linking that model's page
(/models/{provider}/{slug}/) as well is welcome — it points a reader at the
measurement you actually used.
What is the public API?
Four public GET endpoints — three returning JSON, one an SVG image you can embed. None needs an API key or a sign-up, they send CORS headers so a browser page on another origin can read them, and each response is briefly cached so polling faster than the sampling cadence gains nothing.
-
GET /api/healthLiveness and freshness for the benchmark itself: whether the worker is still beating, when the last sample was recorded, and whether that is stale.
curl -s https://api.ollamatps.com/api/health -
GET /api/sites/tokendyno/overviewThe leaderboard as one row per model: latest TPS and time to first token, the 24-hour average, 24-hour reliability with its sample count, the hourly sparkline, the configured base sampling interval, the Artificial Analysis Intelligence Index where a model is matched, and — for OpenCode Go — the request setting the benchmark sends, with a status saying why:
override- set explicitly
selected- chosen automatically as the lowest setting that returned visible text
no-visible-text- no setting returned visible text, so the provider default is sent
pending- not yet verified
unverifiable- a kept setting whose re-verification is currently inconclusive
requestSettingcan also be the literaldefault: the control-free step was itself the lowest setting that returned visible text, which the sites render as “provider default”.requestSettingLostAtis set when a previously verified visible-text setting stopped returning visible text, while the pair still has no verified setting. It is null in that state while a cross-route fallback has found a route that answers and the pair is waiting to be moved there — at most 12 hours after that finding — and null otherwise. All three fields are null for a provider that reports no request setting (Ollama, and the OpenCode Go chat route).intervalMsis the configured base sampling interval for that model, in milliseconds — the cadence the scheduler starts from. It is not a live state. The OpenCode Go budget governor can pause or slow sampling below it while the shared plan budget is being conserved, and an automatic slowdown also lowers the sampling rate of a Go model whose responses run far past the output-token budget it is asked for. Read it as the configured base, not the current rate. The field isnullfor a row whose provider is not registered, where no cadence is claimed.curl -s https://api.ollamatps.com/api/sites/tokendyno/overview -
GET /api/models/{provider}/{slug}/seriesThe time series for one model, at window=24h, 7d, 30d or 1y. A colon in a slug is URL-encoded as %3A.
curl -s 'https://api.ollamatps.com/api/models/ollama/gemma4%3A31b/series?window=24h' -
GET /api/badge/{provider}/{slug}.svgOne model's current tokens per second and the age of the last sample, as a standalone SVG image you can embed in a README or a docs page — paste the Markdown line below. It reads "no recent sample" instead of an old number once the newest successful sample is older than three sampling intervals for that model, and "not currently sampled" for a model we no longer measure. It answers 404 JSON only for an identity TokenDyno has never measured, or for a provider it does not measure. A colon in a slug may be sent as %3A or as __.
[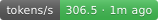](https://tokendyno.com/models/ollama/gemma4__31b/)
What does a response look like?
The overview response, generated from the same published catalog this page was built from:
{
  "site": "tokendyno",
  "rows": [
    {
      "provider": "ollama",
      "slug": "gemma4:31b",
      "displayName": "Gemma4 31B",
      "latestTps": 307.4589261853498,
      "latestTtftMs": 325.7367110000923,
      "lastTestedAt": "2026-11-18T04:50:55.419Z",
      "avgTps24h": 325.19103438787477,
      "successRate24h": 1,
      "sampleCount24h": 142,
      "sparkline": [
        327.66926238106726,
        330.05369913631245,
        305.35115853061905,
        334.6360001026209,
        334.8229879659471,
        320.5842093846007,
        327.3548892204287,
        324.25903322107143,
        331.8615950760609,
        333.52401191227085,
        327.1987996612361,
        328.18728243321806,
        311.01351490189785,
        323.9196838188155,
        331.5252606629305,
        317.02320467335943,
        331.51491337235956,
        326.2025659814558,
        321.0822418350536,
        329.16838904163143,
        343.45488158930425,
        307.04612382740135,
        332.7028159042964,
        320.4992333459698
      ],
      "thinkingCapable": true,
      "aaIntelligence": 4.4,
      "aaUrl": "https://artificialanalysis.ai/models/gemma-4-31b",
      "aaReasoningModel": true,
      "requestSetting": null,
      "requestSettingStatus": null,
      "requestSettingLostAt": null,
      "intervalMs": 600000
    }
  ]
}
Shown with one row; the real response has one row per model.
Which providers and models does the data cover?
TokenDyno measures two platforms, continuously: Ollama Cloud (Pro plan only, because that is the tier we sample) and OpenCode Go. Every row on the leaderboard and in the API is one model on one of those two platforms.
It does not benchmark Cerebras, Groq, SambaNova, OpenRouter, or the first-party APIs of OpenAI, Anthropic and Google, and no numbers for any of those appear in this data. The scope is narrow on purpose: why we cover a narrow set continuously and how each measurement is taken.
How fresh is the data?
Cadence follows how each provider bills, and every string below is derived from the same configuration the worker schedules from rather than typed in. Ollama Pro models are sampled every ~10 minutes; OpenCode Go models are sampled every ~30 minutes for its standard-tier models and every ~6 hours for its most expensive models, and any Go model not yet cleared for the faster tier is held at every ~6 hours. Go sampling may pause or slow below those configured cadences while the shared Go plan budget is being conserved.
The series endpoint is where the history lives: one point per sample or rollup for the window
you ask for. On the overview response, overview.rows[].lastTestedAt is the
timestamp of the last successful measurement for that row, which is how a client tells fresh
data from stale without polling harder.
Frequently asked questions
Can I reuse the TokenDyno data commercially?
Yes. The leaderboard, its measurements and the API responses are published under CC BY 4.0, which permits copying, redistribution and adaptation, including commercial use. Attribution is the only condition: credit TokenDyno and link to the licence.
How do I cite TokenDyno?
Credit TokenDyno, name what you used, and link to https://tokendyno.com/. The citation line on this page adds the CC BY 4.0 deed and the date you accessed the data; if you cite one model, link its model page as well so readers reach the measurement you used.
Does the public API need an API key?
No. The four public GET endpoints documented here need no API key and no sign-up, they send CORS headers so a browser page can read them cross-origin, and three of the four return JSON (the badge returns an SVG image). Responses are briefly cached, so polling faster than the sampling cadence gains nothing.
Which providers are covered?
Ollama Cloud (Pro plan only, because that is the tier we sample) and OpenCode Go. The data does not cover Cerebras, Groq, SambaNova, OpenRouter, or the first-party APIs of OpenAI, Anthropic and Google, and no numbers for those appear in it.