Blog
LLM benchmarking, leaderboards, and inference speed — explained. Definitions, comparisons, and live tokens-per-second analysis from TokenDyno.
- LLM Benchmarking Glossary: Every Term Explained
A clear, sourced glossary of LLM benchmark terms, from MMLU, pass@k, and contamination to tokens/sec, TTFT, and quantization. Built for fast reference.
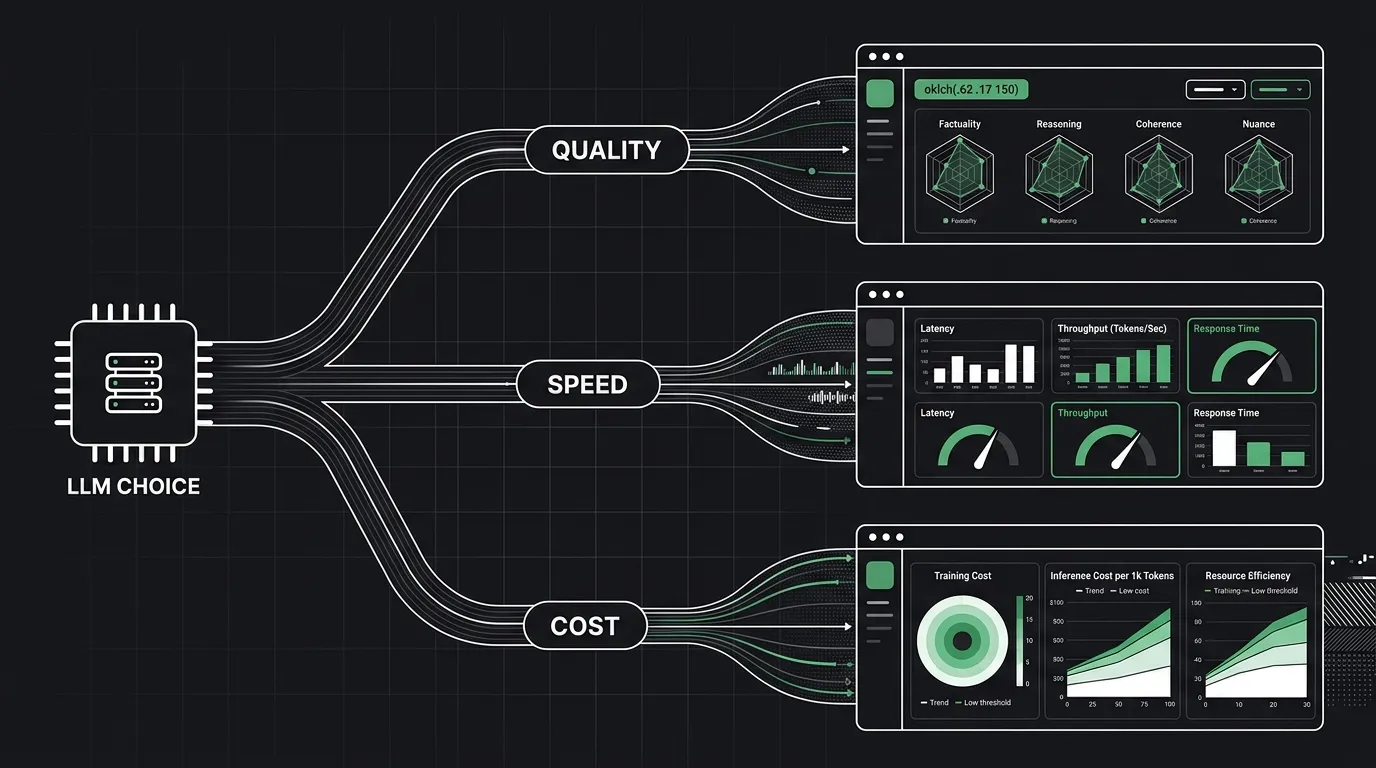
- Speed, Quality, or Both? Choosing the Right LLM Benchmark
A decision framework for what to optimize in an LLM benchmark comparison: quality, speed, or cost, by use case and constraint, with a real 2026 decision matrix.
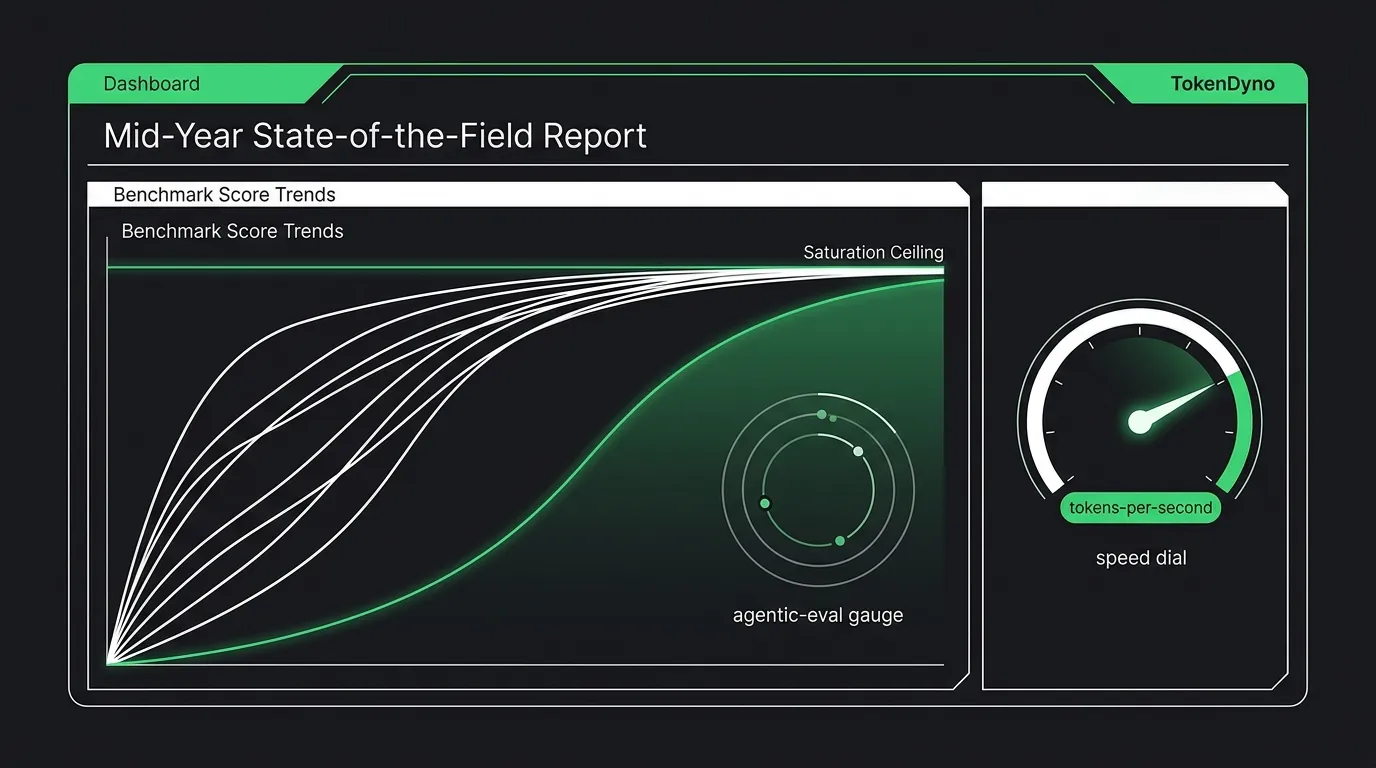
- The State of LLM Benchmarks: 2026 Mid-Year Report
A data-forward mid-2026 report on the state of LLM benchmarks: saturation, the contamination crisis, agentic evals, the speed-cost axis, and AI citations.
- LLM Benchmark Tooling: Run Your Own Tests
A practical roundup of open-source LLM benchmark tooling for capability and speed. What each tool measures, when to use it, and how to install and run it yourself.
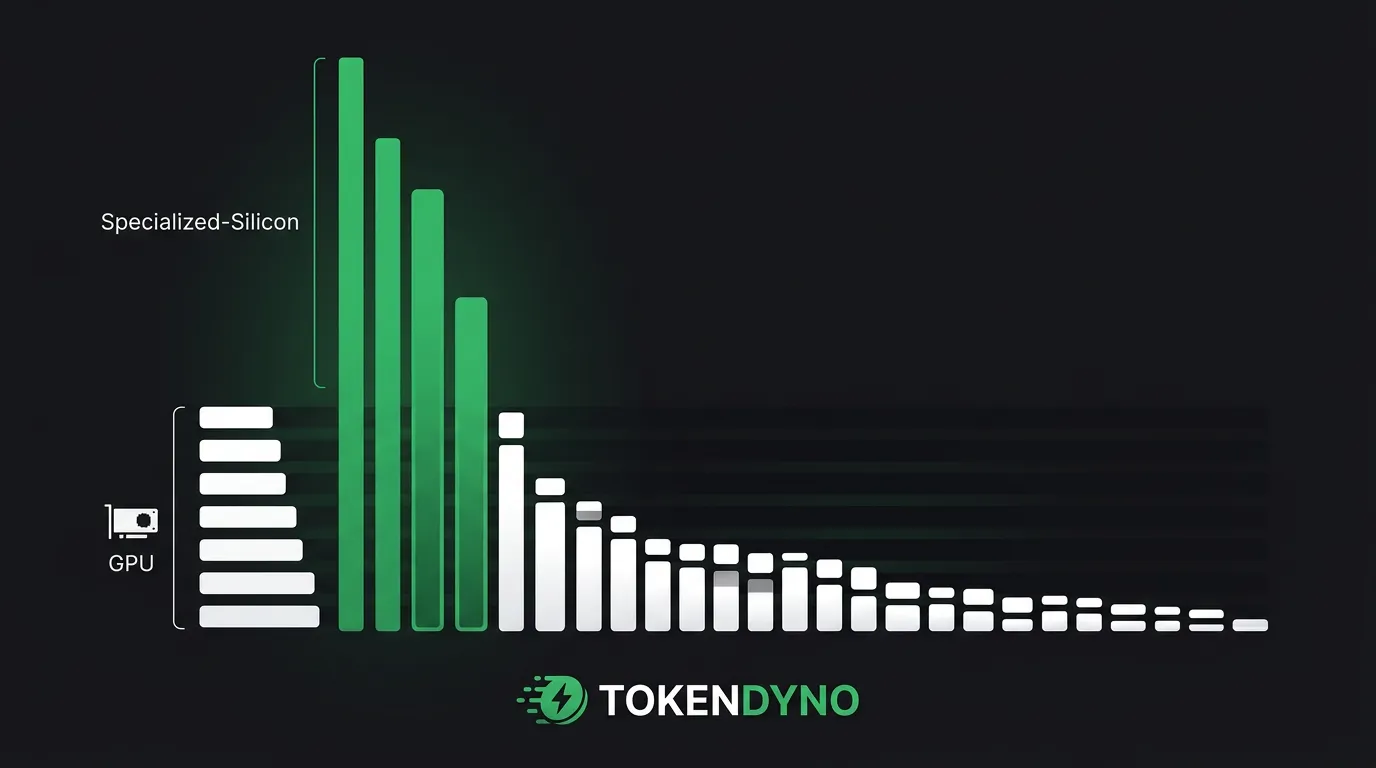
- Provider Throughput Report: Q3 2026 LLM Inference Speeds
A dated Q3 2026 snapshot of LLM inference throughput: which providers lead on output tokens/sec and TTFT, plus the specialized-silicon vs GPU picture.
- Live LLM Benchmark Updates: How Freshness Changes Rankings
Benchmark freshness changes LLM rankings: monthly refreshes, new model drops, and provider quantization or routing shifts reshuffle standings through 2026.
- GPU Benchmark for LLMs: How Hardware Shapes Throughput
A GPU benchmark for LLMs explaining how memory bandwidth, VRAM, FLOPs, and interconnect shape tokens/sec across H100, H200, B200, GB200, MI300X, Groq, and Cerebras.
- Coding Benchmark LLM: Evaluating Code Models in 2026
A practitioner's guide to evaluating code-generation LLMs in 2026: what to test, how to run your own eval with Inspect AI and EvalPlus, and reading scores critically.
- LLM Coding Benchmark Leaderboard: Code Generation Rankings
A guide to the leaderboards that rank LLM coding ability: SWE-bench, Aider polyglot, LiveCodeBench, BigCodeBench, and Terminal-Bench, with live links.
- LLM Creative Writing Benchmark: How Models Score on Prose
How an LLM creative writing benchmark scores subjective prose: EQ-Bench, LMArena style control, judge-based eval and its biases, and human review, with live sources.
- Best LLM Benchmark: Which to Use for Your Use Case
No single LLM benchmark is best. This roundup maps coding, reasoning, chat, RAG, agents, latency, and cost to the right benchmark, plus a caveat for each.
- LLM Benchmark Comparison: Side-by-Side Model Evaluation
Run an LLM benchmark comparison correctly: build a per-axis framework, normalize and weight scores, avoid contamination traps, with a real side-by-side.
- Why Tokens/sec Belongs in Every LLM Ranking
A sourced case that LLM speed (tokens/sec, TTFT) is a first-class evaluation axis beside capability, because latency compounds across agentic and real-time use.
- Why 'LLM Leaderboard' Searches Land on Aggregators (and What's Missing)
A sourced analysis of the 'llm leaderboard' SERP: why aggregators like Artificial Analysis and LMArena dominate, what searchers want, and the live-speed gap.
- LLM Benchmark Leaderboard: Quality vs Speed Rankings
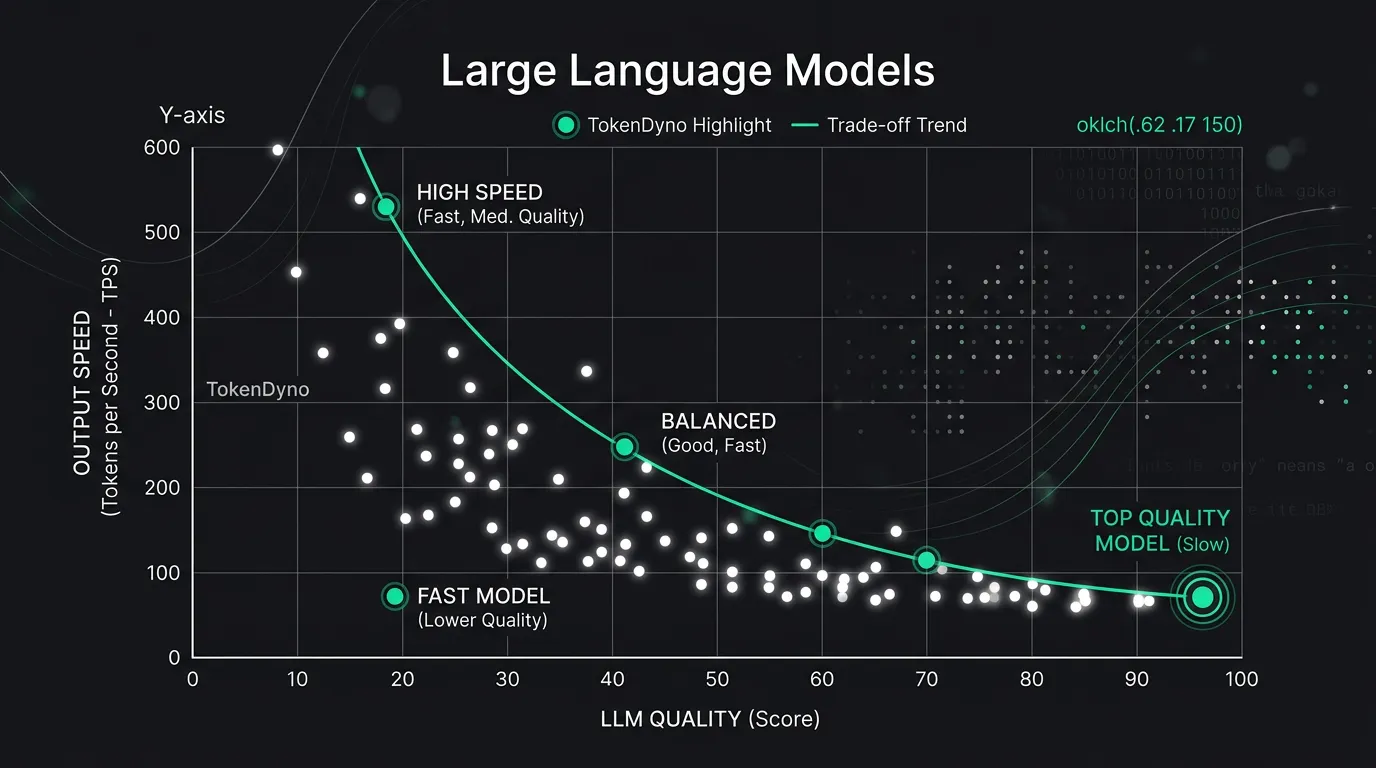
Most LLM leaderboards rank quality; few rank speed. Verified 2026 data: the smartest model runs ~62 tokens/sec while the fastest streams 850+. Read both axes.
- AI Overviews and LLM Leaderboards: How to Get Cited by AI Search
How Google AI Overviews, ChatGPT, Perplexity, and Gemini decide which leaderboards to cite, and what makes benchmark data citable in AI search in 2026.
- LiveBench vs Artificial Analysis vs TokenDyno: Which LLM Benchmark Fits Your Need?
An honest comparison of LiveBench, Artificial Analysis, and TokenDyno: what each LLM benchmark measures, how often it refreshes, and which one fits your need.
- LLM Leaderboards Compared: Which Ranking Should You Trust?
LMArena, Artificial Analysis, LiveBench, HELM, SWE-bench and Vellum compared by method, gameability, and cadence — and which to trust for which question.
- LLM Benchmarks: The Full 2026 Landscape
The 2026 LLM benchmark landscape, organized by what each test reveals, with a one-line 'why it matters' and current status (active, saturated, or contested) for every entry.
- LLM Benchmark: A Complete Guide to Model Evaluation
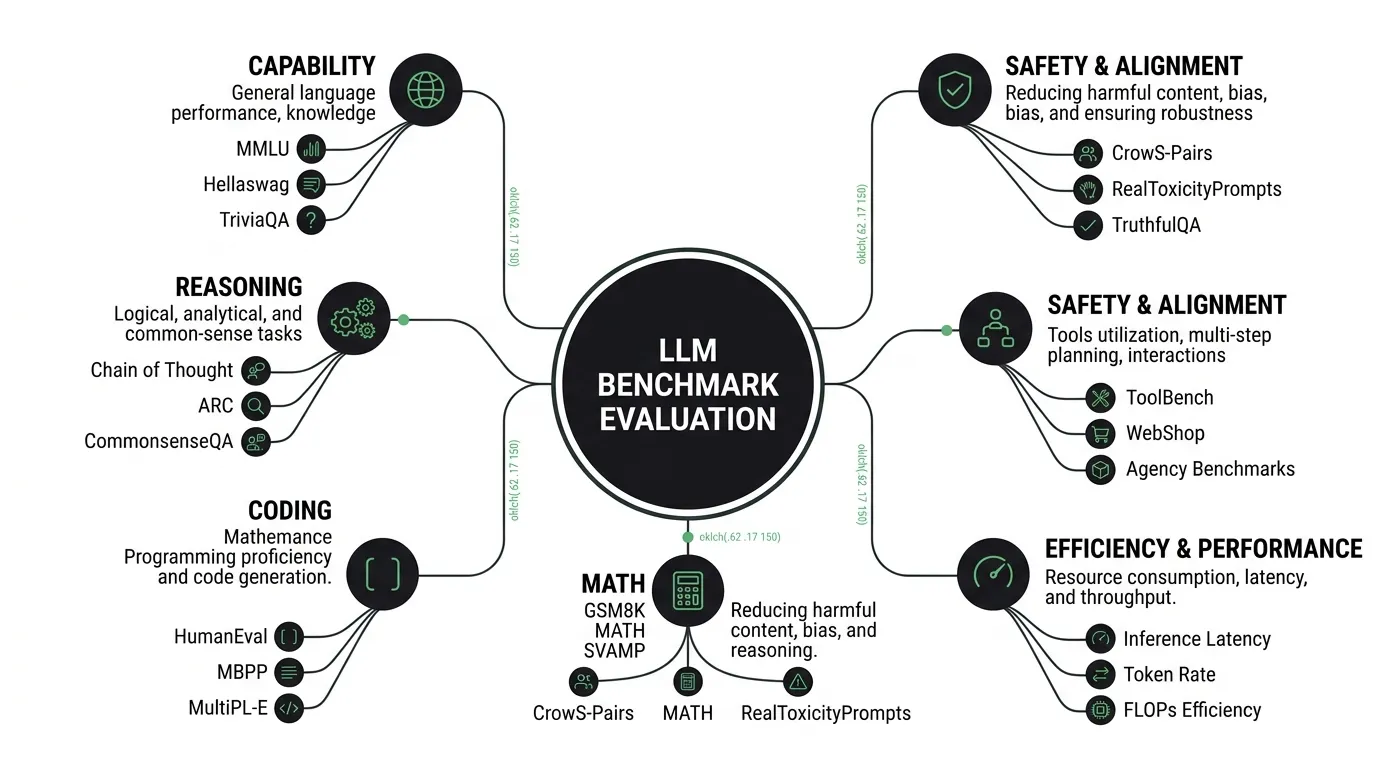
The complete 2026 guide to LLM benchmarks: what they are, the full taxonomy across capability, reasoning, coding, math, safety, agentic, and speed, plus limitations and how to choose one.
- AI Benchmarking: Methodologies, Datasets, and the Speed Layer
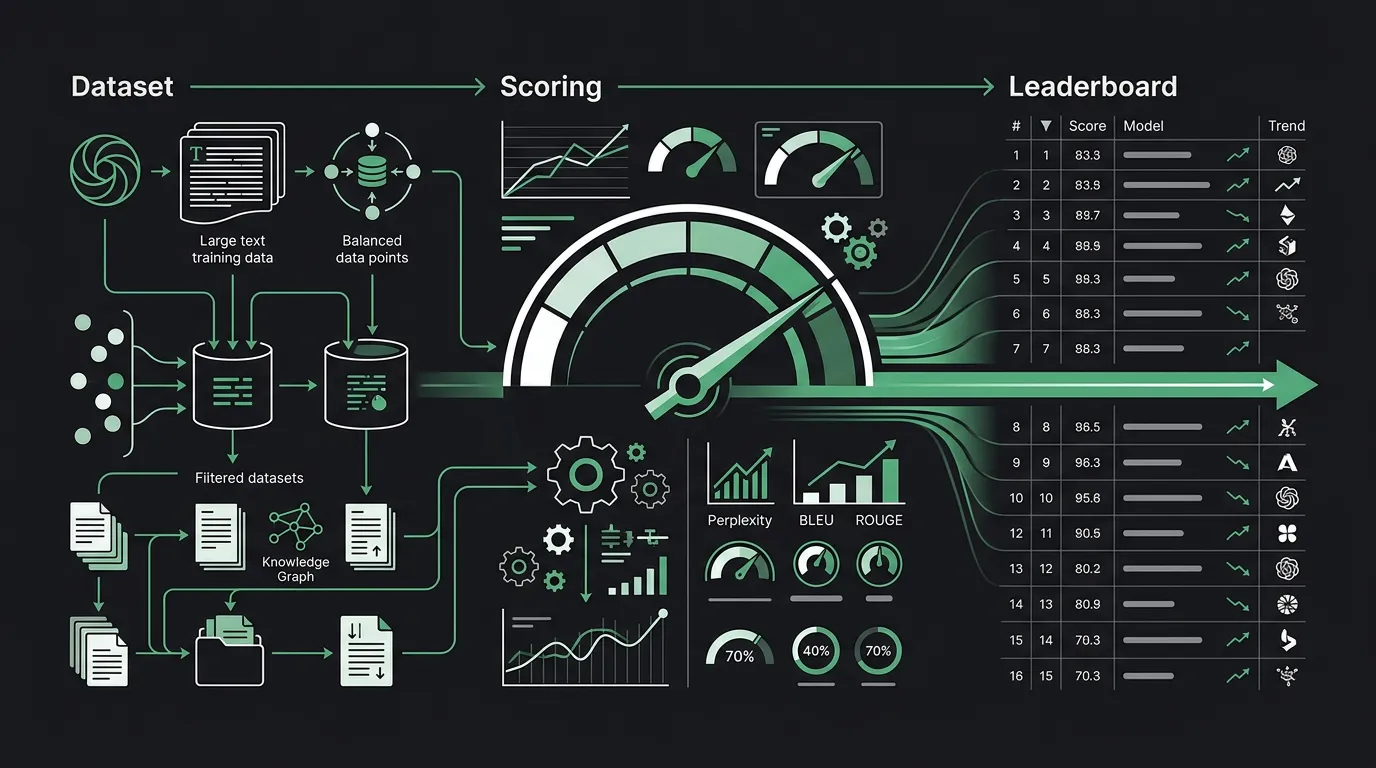
How AI benchmarking actually works: dataset construction, evaluation protocols, scoring, contamination controls, reproducibility standards, and the speed layer.
- AI Benchmark 2026: What It Is and Why Demand Grew 84%
An AI benchmark is a standardized test scoring how well AI reasons, codes, or perceives. See the major categories, the hardest 2026 tests, and saturation.
- LLM Benchmark Leaderboard: How Rankings Are Built
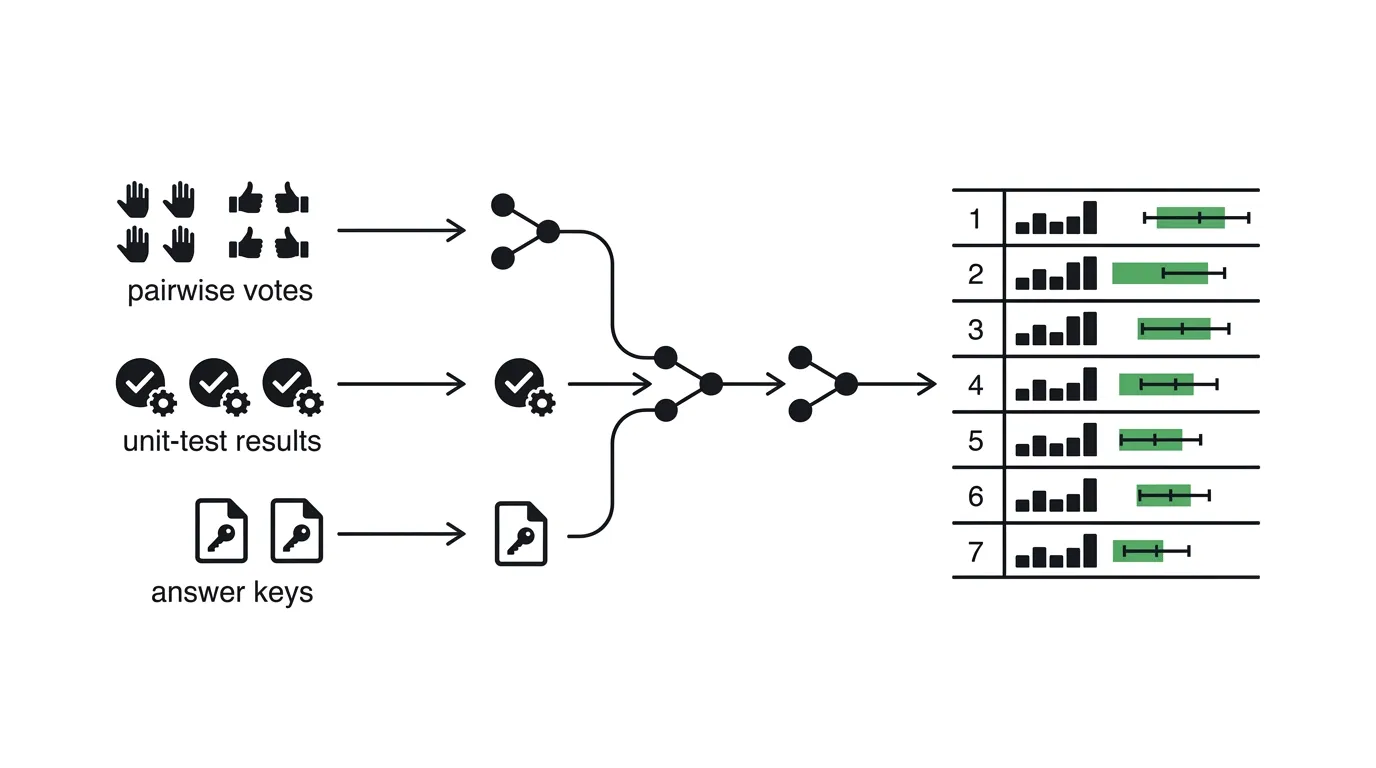
How are LLM benchmark leaderboards built? A data-forward guide to Elo/Bradley-Terry, pass@k, normalized accuracy, confidence intervals, and contamination controls.
- LLM Leaderboard 2026: The Live Tokens/sec Ranking
The definitive 2026 guide to LLM leaderboards: LMArena, Artificial Analysis, HELM, LiveBench, SWE-bench, how to read them, their biases, and the missing speed metric.
- What Is LLM Benchmarking? Why Speed Metrics Now Matter
LLM benchmarking is the standardized testing of language models against fixed datasets and scores. Learn how it works, plus why speed now decides which model wins.
- LLM Coding Benchmark: How Models Compare on Code
How LLM coding benchmarks work: SWE-bench, HumanEval, LiveCodeBench, Aider polyglot, and Terminal-Bench compared, including pass@k, contamination, and live leaders.
- Examples of LLM Benchmarks: A Field Guide (Quality + Speed)
A categorized field guide to real LLM benchmark examples: reasoning, coding, math, knowledge, agentic, human-preference, and speed, each with what it measures and who maintains it.
- Which LLM Performs Best on Benchmarks? Speed vs Accuracy
No single LLM wins every benchmark. See how to find the best model on each axis—reasoning, coding, math, speed, cost—using live 2026 leaderboards.
- LLM Inference Speed Benchmark: Methodology and Metrics
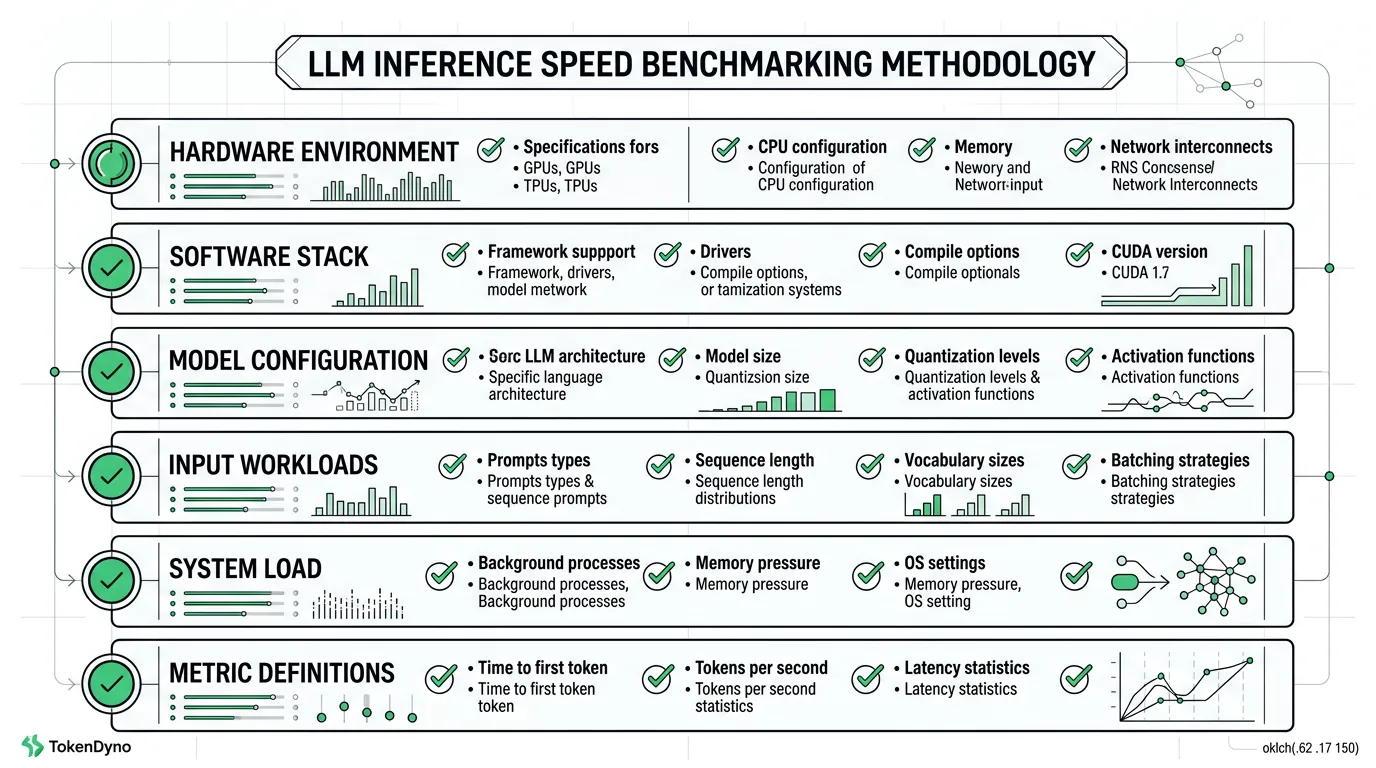
How to benchmark LLM inference speed correctly: the variables that make most tokens/sec comparisons misleading, plus a methodology checklist and metrics.
- LLM Throughput Benchmark: Tokens/sec by GPU and Provider
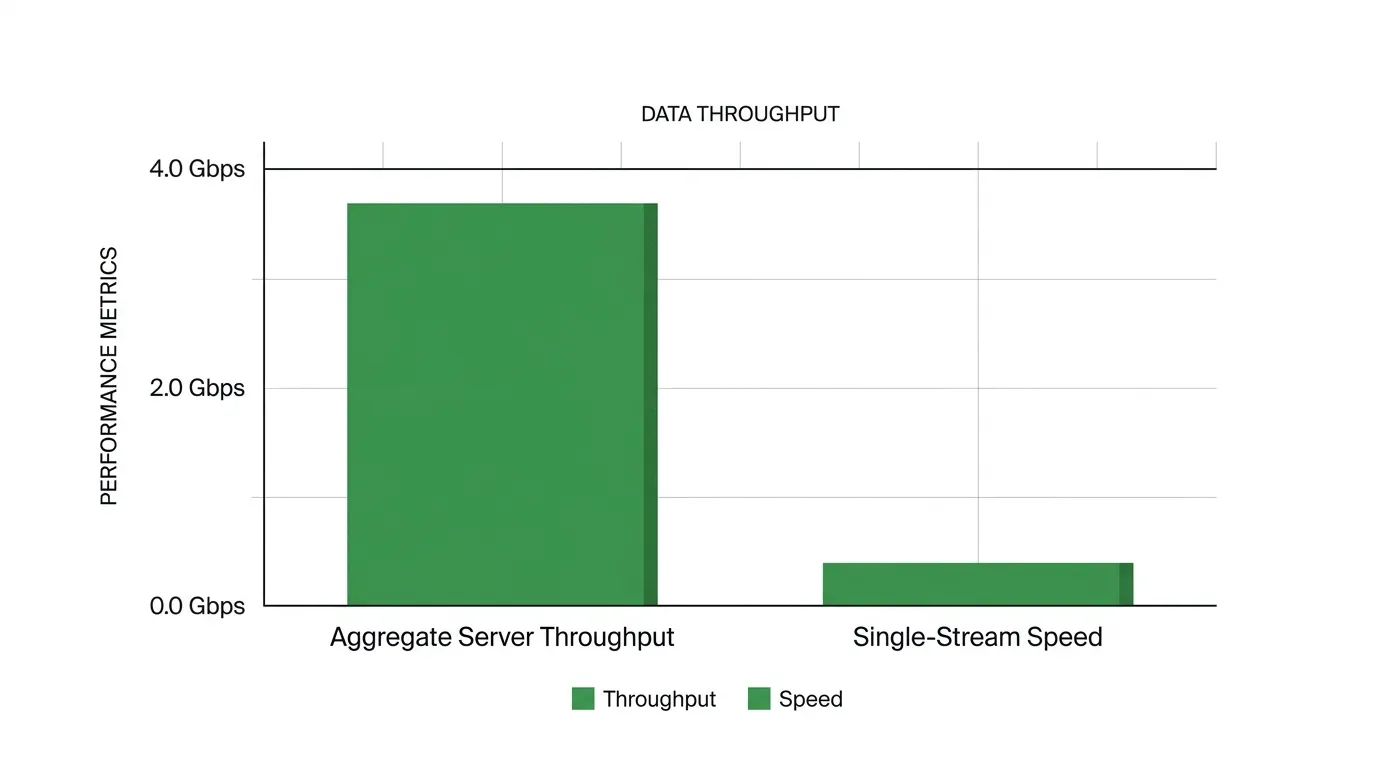
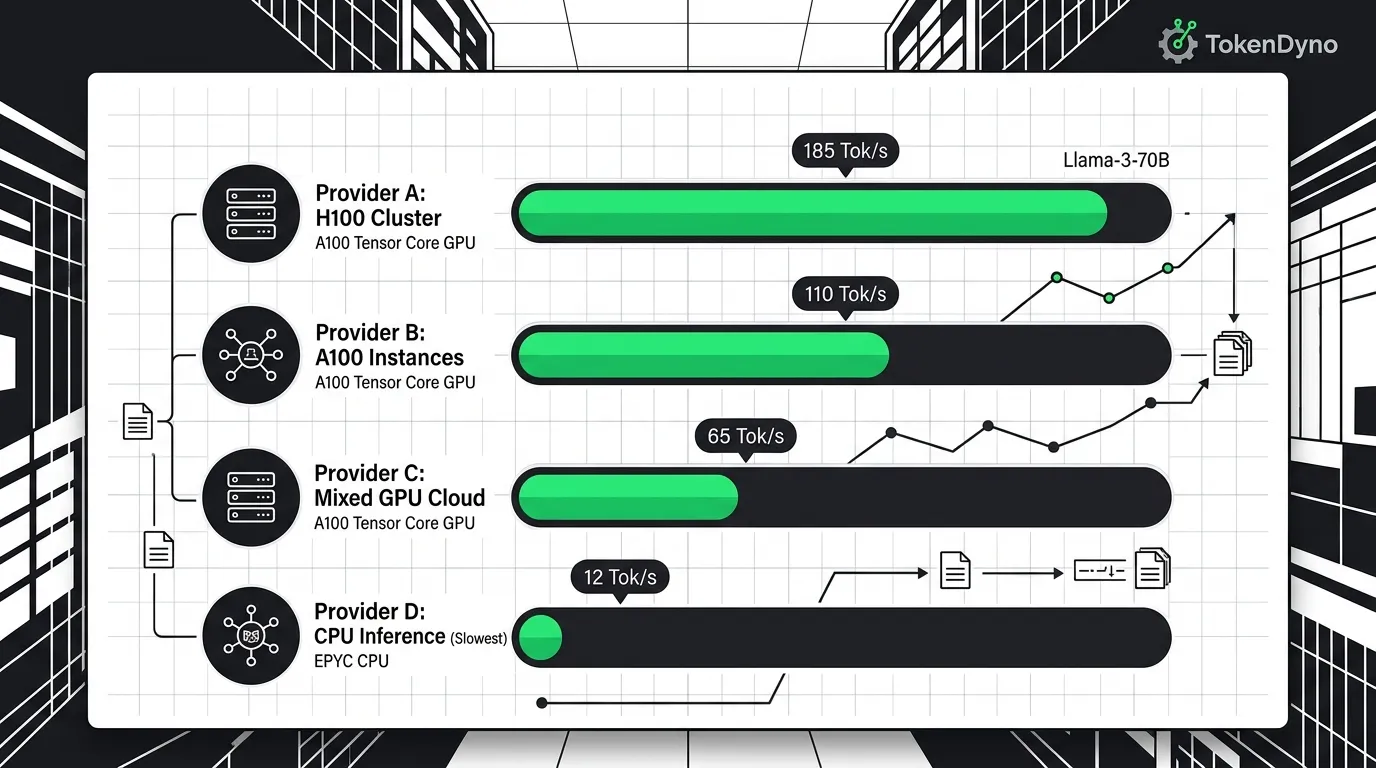
An LLM throughput benchmark of tokens/sec by GPU and provider. Aggregate vs single-stream, batching, and how H100/H200/B200/GB200, Groq, Cerebras compare.
- LLM Speed Comparison: Throughput Across Models and Providers
An LLM speed comparison across models and providers using real output tokens/sec from Artificial Analysis: why the same model runs 3x to 33x faster by host.
- LLM Latency Benchmark: Time-to-First-Token Explained
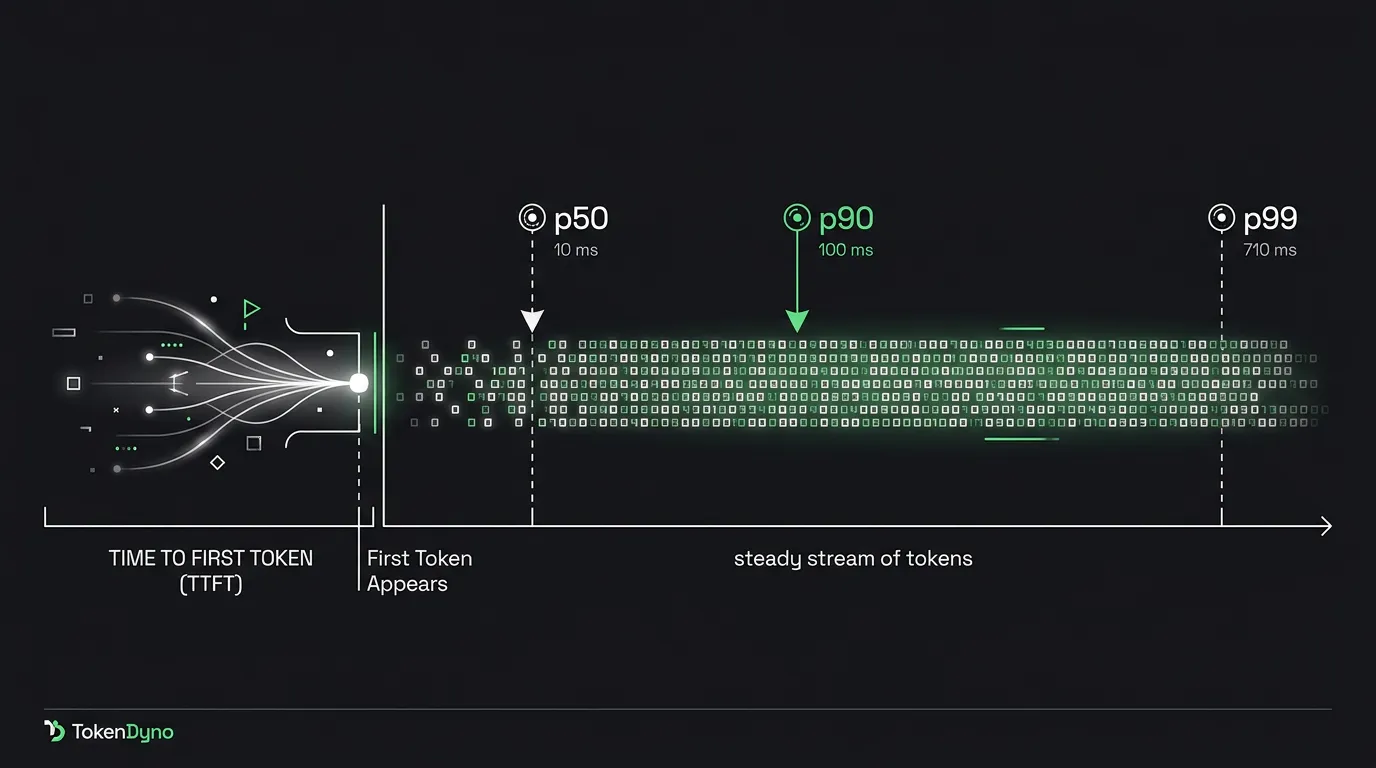
An LLM latency benchmark measures TTFT, inter-token latency, and tail latency, not throughput. Real p50/p90/p99 figures across providers and how to measure each.
- LLM Inference Benchmark: Speed vs Quality Trade-offs
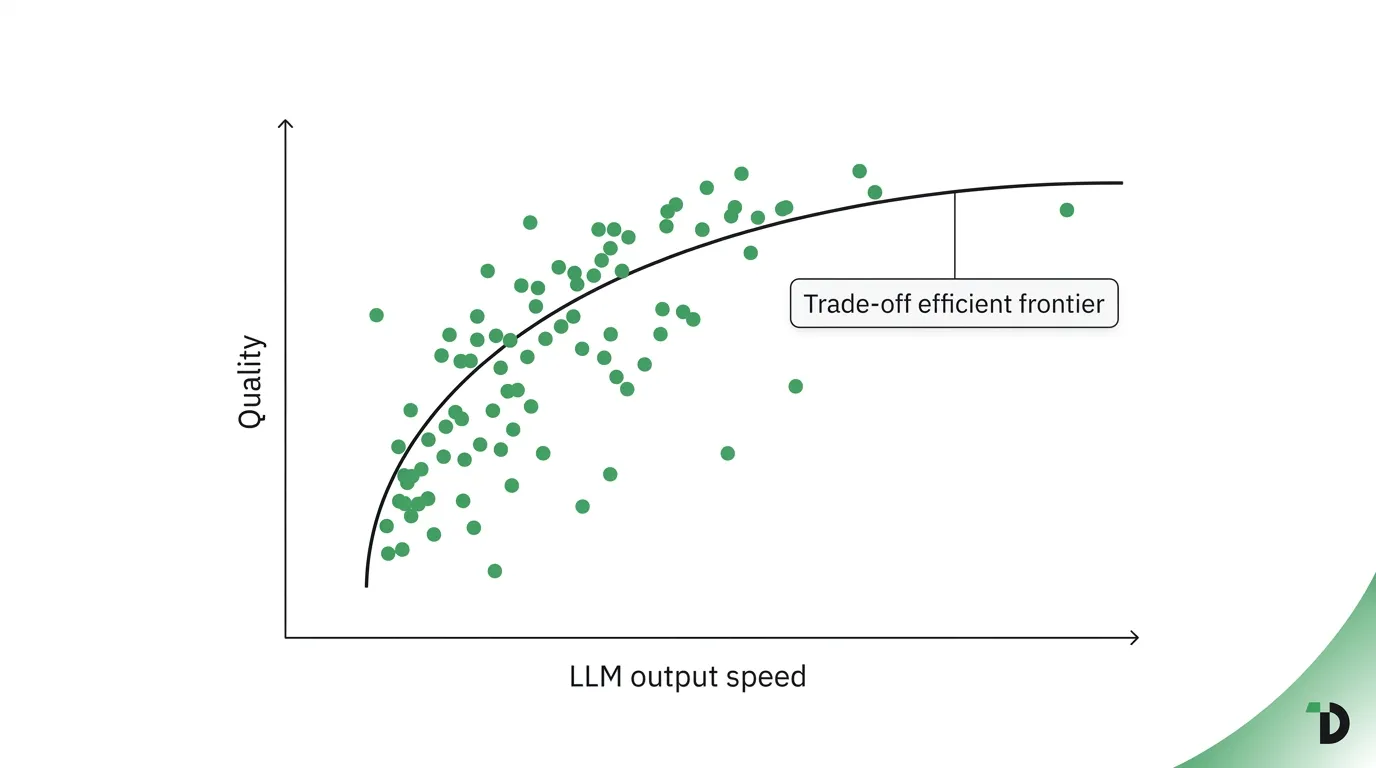
How LLM inference benchmarks measure speed: tokens/sec, TTFT, and latency, and why the speed-quality-cost frontier means faster inference isn't always better.
- Fastest LLM Inference in 2026: Live Tokens/sec Leaderboard
The fastest LLM inference in 2026, ranked by real output tokens/sec from Artificial Analysis. Live leaderboard, hardware breakdown, and the speed-quality tradeoff.
- LLM Tokens Per Second: How to Measure Inference Speed
How to measure LLM tokens per second: prefill vs decode, TTFT, inter-token latency, tokenizer caveats, and real 2026 throughput numbers you can verify.
- What Is an LLM Benchmark? Definition, Types, and How They Work
An LLM benchmark is a standardized test that scores how well language models reason, code, and answer. Learn the types, real examples, and how they work.